What We Measured Routing GPT-4o Traffic to Cheaper Models
Early first-party data from PromptUnit's own tests: how often a cheaper model matched the one the app chose in 24 comparisons, what it cost, and the limits.
When teams integrate GPT-4o into a product, they usually start with one model for everything. It is the pragmatic choice: you need the product to work before you optimize it.
The problem is that "start with GPT-4o for everything" quietly becomes "run GPT-4o for everything forever", and the hidden cost of that default only shows up when the monthly invoice gets uncomfortable.
PromptUnit sits in the request path of live products, so instead of guessing, we can measure. The figures below are early data from our own tests on one production account (the methodology is at the end). The sample is small, so read them as early signals, not benchmarks.
Most production traffic is simple
The first thing the data shows is that this traffic is not uniformly hard. The large majority of it is short, bounded work.
Of the 183 live requests from one production account between October 2 and 7, 2026 (PromptUnit's own classifier assigns the task types, so they are approximate):
- About 83% is simple question-answering: support replies, short summaries, straightforward lookups.
- About 7% is domain-specific work.
- About 6% is heavy reasoning or complex code generation.
- About 3% is classification and intent detection, and about 1% is creative writing.
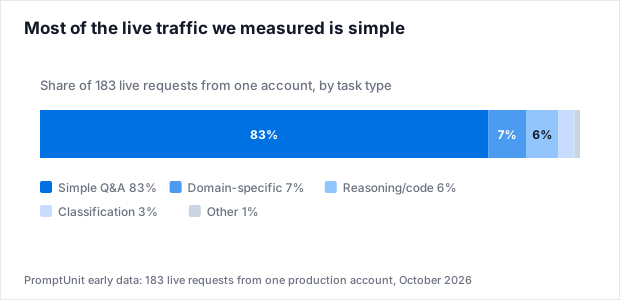
In other words, the expensive, frontier-grade tasks are real, but they are the minority of requests. Most requests are simpler than the model running them.
How often a cheaper model is actually good enough
Knowing the traffic is simple is not enough. The real question is whether a cheaper model holds the quality. So for a sample of real requests we run the cheaper model on the same prompt and ask the model the app chose to judge whether the cheaper answer holds up.
What we measured, across 24 comparisons:
- A cheaper model matched or beat the chosen model in 18 of 24 (75%).
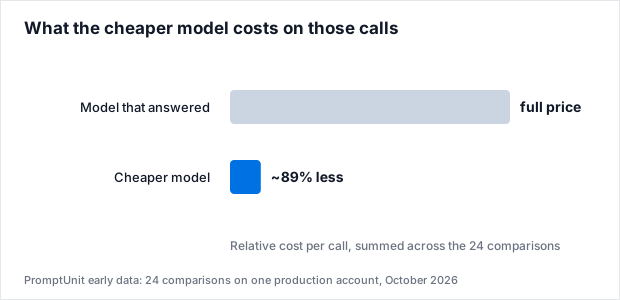
- Across all 24 comparisons, the cheaper models cost roughly 89% less than the models that answered.
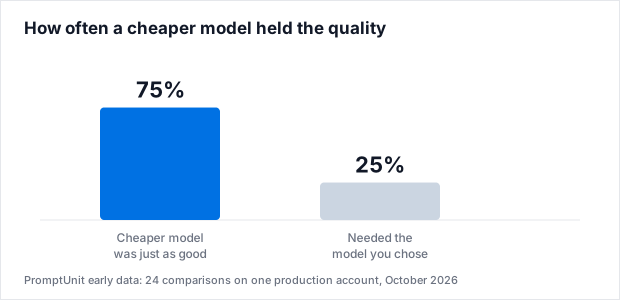
The gap between models is not small. Measured by provider list prices, the difference between a frontier model and an efficient one runs from about 17x to over 100x per token. So when a cheaper model does hold the quality, the saving on that call is large.
It depends on the pair
Not every swap is equal, and the data makes that clear (the counts are small, so read them as early signals):
- Claude Sonnet 5 to Gemini 2.5 Flash matched the chosen model in 9 of 10 comparisons. This was the strongest pair.
- Claude Sonnet 5 to GPT-5.4 mini matched in 8 of 10.
- Swaps below Claude Haiku 4.5 (Gemini 2.5 Flash-Lite and GPT-4o-mini) matched in 1 of 4 and need more care.
This is exactly why routing has to be checked per task and per pair, not assumed. A blanket "always use the cheap model" rule gives back quality you did not mean to trade.
The cost arithmetic
The reason the savings are worth chasing is the price spread. At current pricing (GPT-4o: $2.50/M input, $10.00/M output; GPT-4o-mini: $0.15/M input, $0.60/M output):
| Scenario | GPT-4o cost | GPT-4o-mini cost | Difference |
|---|---|---|---|
| 1,000 input tokens | $0.0025 | $0.00015 | ~17x cheaper |
| 1,000 output tokens | $0.01 | $0.0006 | ~17x cheaper |
| Full call (1K in, 500 out) | $0.0075 | $0.00045 | ~17x cheaper |
The same pattern holds for the newer tiers (GPT-5 and GPT-5 mini, Claude Sonnet and Haiku, Gemini Pro and Flash): a large price gap between the strong model and the efficient one, and a lot of traffic that does not need the strong one.
Routing a share of your traffic to a cheaper model does not cut the bill by that same share, because the routed calls are often smaller. Our estimate for total savings is 40% to 70% of spend on a workload that is mostly simple requests. That is an estimate, not a measurement: on the one live account we have data for, 34% of requests (63 of 183) were answered by a cheaper model and the bill was about 11% lower than it would have been on the models the app asked for, because most of that account's spend is long writing steps that stay on the stronger model. Your number depends on your token distribution and task mix.
Let each request use the cheapest model that's just as good
PromptUnit checks each request your app sends. When a cheaper model is just as good for that request, it uses it; otherwise your model answers. Free until it has saved you money.
Try it free →The tasks that route well
Across the traffic we see, the same categories route down cleanly:
Summarization. The task is bounded: take a longer text, produce a shorter one that keeps the key points. Efficient models handle this well across support tickets, reviews, and transcripts.
Classification and intent. "Is this a complaint, a question, or a compliment?" "Which category does this belong to?" These are short, well-defined, and have a ground truth to check against. They play to the strengths of smaller models.
Structured extraction. Pulling dates, names, and fields into clean JSON is pattern work, not deep reasoning. With an explicit schema, efficient models match the strong ones on the simpler cases.
Customer support replies. This one surprises teams most. With a good system prompt, a smaller model produces replies customers cannot reliably tell apart from the expensive model's. The quality ceiling here is usually the system prompt, not the model.
The tasks that still need a frontier model
Being clear about where smaller models fall short matters just as much.
- Non-trivial code generation. Multi-file refactors, tricky algorithms, and subtle debugging need the reasoning depth of a frontier model.
- Long-context reasoning. Tracking dozens of facts across a large context window, legal analysis, big-codebase comprehension.
- Creative and brand-sensitive content. When quality is a brand differentiator and there is no ground truth to test against, default to the best model.
- Multi-step agent chains. Plan-execute-correct loops degrade noticeably on smaller tiers.
These high-value tasks are the minority. Routing everything else to cheaper models does not compromise them; it funds them.
How routing works in practice
Model routing classifies each request before it reaches the model, using complexity signals (token count, presence of code, instruction complexity), the task type, and how similar requests have held up on cheaper models before. The classification adds single-digit milliseconds.
With an OpenAI-compatible proxy like PromptUnit, the integration is a single base URL change:
from openai import OpenAI

client = OpenAI(
    api_key="sk-...",
    base_url="https://www.promptunit.ai/api/proxy/openai",
    default_headers={"x-promptunit-key": "YOUR_KEY"},
)

# All existing calls work unchanged
response = client.chat.completions.create(
    model="gpt-4o",  # PromptUnit routes this when a cheaper model is just as good
    messages=[{"role": "user", "content": "Summarize this support ticket..."}]
)
Your application code, error handling, and response parsing do not change.
What you see from the first request
Savings start with the first request. Every request is checked. When a cheaper model is just as good for it, PromptUnit uses it; when it is not, the request goes to the model you asked for. Each request shows on the dashboard within seconds, with the model you asked for, the model that answered, what it cost, and what it saved. If PromptUnit saves nothing, you pay nothing.
The header x-promptunit-routing: off keeps a request on the model you asked for. For the full walkthrough, see OpenAI API Cost Too High? Six Fixes, Ordered by Effort.
Key takeaways
- In our early data from one account, most requests are simple: about 83% are basic question-answering, and about 6% are heavy reasoning or complex code.
- In 24 side-by-side comparisons, a cheaper model matched or beat the chosen one 18 times (75%), at roughly 89% lower cost on those calls.
- The best swap depends on the pair: Claude Sonnet 5 to Gemini 2.5 Flash matched 9 of 10 times; drops to the very smallest models need more care.
- Our estimate of total bill reduction is 40-70% for a workload that is mostly simple requests. It is an estimate, not a measurement: on the one live account we have, the bill was about 11% lower.
- The only way to know your number is to measure against your own traffic.
For the full strategy, see LLM Model Routing: The Complete Guide. For the compounding cost of not routing, see The Hidden Cost of Defaulting to GPT-4o. For extending savings across providers, see Cross-Provider LLM Routing.
How we measured this
These figures are early data from one production account, not a benchmark. Here is exactly what is behind them (updated October 7, 2026):
- Sample. 24 side-by-side comparisons between October 5 and 7, 2026, all from one production account, plus 183 live requests from the same account between October 2 and 7.
- How a comparison works. For a sample of real requests, PromptUnit runs a cheaper model on the same prompt after the answer has gone back to the app, and asks the model the app chose to judge whether the cheaper answer holds up. In all 24 comparisons the judge was Claude Sonnet 5, the model the app had asked for, so the verdicts measure agreement with that model, not an outside benchmark. In 20 of the 24 comparisons the model that answered was Claude Sonnet 5; in 4 it was Claude Haiku 4.5, which PromptUnit had already switched to.
- Results. The cheaper model matched or beat the chosen model in 18 of 24 comparisons (75%). Together the cheaper models cost about 11% of what the models that answered cost on the same calls, which is about 89% less. By pair: Claude Sonnet 5 to Gemini 2.5 Flash matched 9 of 10, Sonnet 5 to GPT-5.4 mini matched 8 of 10, and swaps below Claude Haiku 4.5 (Gemini 2.5 Flash-Lite and GPT-4o-mini) matched 1 of 4.
- Traffic mix. Of the 183 live requests, about 83% were labeled simple question-answering and about 6% reasoning or complex code. PromptUnit's own classifier assigns these labels, so they are approximate.
- Savings on the real bill. On those 183 requests, 34% (63) were answered by a cheaper model, and the bill was about 11% lower than it would have been on the models the app asked for. The 40 to 70 percent range we quote is an estimate, not a measurement. It assumes a workload that is mostly simple requests, and this account is mostly long writing steps that stay on the stronger model.
- Privacy. We store only metadata (task type, models, cost, verdict), never prompt or response text.
- Limits. A sample of 24 is small: with 18 of 24, the true match rate could plausibly be anywhere from roughly 55% to 88%. One account is not representative of all AI applications, and the numbers will move as more traffic runs through. We update this section as the data grows.
Try it free
See exactly where your AI budget is going. PromptUnit shows every request with the model that answered, what it cost and what it saved, starting with your first one.
Start free, no credit card needed. Or talk to us if you want a walkthrough.